Search guru Bruce Croft gave a keynote talk at CIKM 2008 titled "Unsolved Problems in Search (and how we might approach them)".
The talk started with a bit of a pat on the back for those working on search, with Bruce saying that "search is everywhere" -- not just the web, but enterprise, desktop, product catalogs, and many other places -- and, despite hard problems of noisy data and vocabulary mismatch between what searchers actually want and how they express that to a search engine, search seems to do a pretty good job.
But then, Bruce took everyone to task, saying that current search is nothing like the "vision of the future" that was anticipated decades back. We still are nowhere near a software agent that can understand and fulfill complex information needs like a human expert would. Bruce said the "hard problems remain very hard" and that search really only works well when searchers are easily able to translate their goals into "those little keywords".
To get to that vision, Bruce argued that we need to be "evolutionary, not revolutionary". Keep chipping away at the problem. Bruce suggested long queries as a particularly promising "next step toward the vision of the future", saying that long queries work well "for people [not] for search engines", and discussed a few approaches using techniques similar to statistical machine translation.
It may have been that he ran short on time, but I was disappointed that Bruce did not spend more time talking about how to make progress toward the grand vision of search. A bit of this was addressed in the questions at the end. One person asked about whether search should be more of a dialogue between the searcher and the search engine. Another asked about user interface innovations that might be necessary. But, in general, it would have been interesting to hear more about what new paths Bruce considers promising and which of the techniques currently used he considers to be dead ends.
On a side note, there was a curious contrast between Bruce's approach of "evolutionary not revolutionary" and the "Mountains or the Street Lamp" talk during industry day. In that talk, Chris Burges argued that we should primarily focus on very hard problems we have no idea how to solve -- climb the mountains -- not twiddles to existing techniques -- look around nearby in the light under the street lamp.
Bruce's keynote talk should appear on videolectures.net in a couple weeks.
Friday, October 31, 2008
Tuesday, October 28, 2008
Rakesh Agrawal at CIKM 2008
Rakesh Agrawal from Microsoft Research gave a keynote talk yesterday morning at CIKM 2008 on Humane Data Mining. Much of the talk was on the potential of data mining in health care, but I am going to highlight only the part on web search, particularly the talk's notable focus on serendipity, discovery, and diversity in web search.
When talking about web search, Rakesh first mentioned making orthogonal query suggestions to support better discovery. The idea here is that searchers may not always know exactly what they want. The initial query may just be a starting point to explore the information, learn what is out there, and figure out what they really want to do. Suggesting queries that are related but a bit further afield than simple refinements may help people who don't know quite what they need to get to what they need.
Rakesh then talked briefly about result diversification. This is particularly important on ambiguous queries, but also is important for ambiguous tasks, where a searcher doesn't quite know what he wants and needs more information about what information is out there. Rakesh mentioned the long tail of search results as part of improving diversity. He seemed surprisingly pessimistic about the ability of recommender system approaches to surface items from the tail, either in products or in search, but did not elaborate.
Finally, learning from click data came up repeatedly, once in learning to classify queries using similarities in click behavior, again in creating implicit judgments as a supplement or replacement for explicit human judges, and finally when talking about a virtuous cycle between search and data where better search results attract more data on how people use the search results which lets us improve the results which gives us more data.
The talk was filmed by the good people at videolectures.net and should be available there in a couple weeks.
Please see also some of my past posts on related topics, including "Evaluating search result pages", "Learning diversity when learning to rank", "Personalization, Google, and discovery", and "Recommender systems and diversity".
Friday, October 24, 2008
Evaluating search result pages
Yahoo Chief Scientist Jan Pedersen recently wrote a short position paper, "Making Sense of Search Result Pages" (PDF), that has some interesting tidbits in it. Specifically, it advocates for click-based methods for evaluating search result quality and mentions using toolbar data to see what people are doing after leaving the search result page.
Some extended excerpts:
For more on using click-based methods to evaluate search results, please see a post by Googler Ben Gomes, "Search experiments, large and small" as well as my previous posts, "Actively learning to rank" and "The perils of tweaking Google by hand".
By the way, rumor has it that Jan Pedersen left Yahoo and is now at A9. Surprisingif true.
Update: Rumor confirmed. Jan Pedersen is now at A9.
Some extended excerpts:
Search engine result pages are presented hundreds of millions of times a day, yet it is not well understood what makes a particular page better from a consumer's perspective. For example, search engines spend large amounts of capital to make search-page loading latencies low, but how fast is fast enough or why fast is better is largely a subject of anecdote.For more on how search engines may be using toolbar data, please see my previous post, "Google Toolbar data and the actual surfer model".
Much of the contradiction comes from imposing a optimization criterion ... such as discounted cumulative gain (DCG) ... that does not account for perceptual phenomena. Users rapidly scan search result pages ... and presentations optimized for easy consumption and efficient scanning will be perceived as more relevant.
The process Yahoo! search uses to design, validate, and optimize a new search feature includes ... an online test of the feature ... [using] proxy measures for the desired behaviors that can be measured in the user feedback logs.
Search engine query logs only reflect a small slice of user behavior -- actions taken on the search results page. A more complete picture would include the entire click stream; search result page clicks as well as o ffsite follow-on actions.
This sort of data is available from a subset of toolbar users -- those that opt into having their click stream tracked. Yahoo! has just begun to collect this sort of data, although competing search engines have collected it for some time.
We expect to derive much better indicators of user satisfaction by consider the actions post click. For example, if the user exits the clicked-through page rapidly then one can infer that the information need was not satisfied by that page.
For more on using click-based methods to evaluate search results, please see a post by Googler Ben Gomes, "Search experiments, large and small" as well as my previous posts, "Actively learning to rank" and "The perils of tweaking Google by hand".
By the way, rumor has it that Jan Pedersen left Yahoo and is now at A9. Surprising
Update: Rumor confirmed. Jan Pedersen is now at A9.
Thursday, October 23, 2008
Cross-site request exploits
Bill Zeller and Ed Felten have an interesting paper, "Cross-Site Request Forgeries: Exploitation and Prevention" (PDF), that looks at exploiting the implicit authentication in browsers to take actions on the user's behalf using img tags or Javascript.
The most dramatic of the attacks allowed the attacker to take all the money from someone's ING Direct account just by visiting a web page. The attack sent POST requests off to ING Direct using Javascript, so they appear to come from the victim's browser. The POST requests quickly and quietly cause the victim's browser to create a new account by transferring money from their existing account, add the attacker as a valid payee on the new account, then transfer the funds to the attacker's account. Danger, Will Robinson.
Please see also Bill Zeller's blog post describing the attack and the Wikipedia page for cross-site request forgery.
[Paper found via Bruce Schneier]
Wednesday, October 22, 2008
A 2008 dot-com crash
Richard Waters and Chris Nuttall at the Financial Times write: They also say that "Sequoia Capital ... [recently] greeted [entrepreneurs] with a presentation that began with a slide showing a gravestone and the words 'RIP good times' and were told to treat every dollar they spent as though it was their last."
Please see also my January 2008 post, "The coming 2008 dot-com crash", the predictions there, and the many comments on that post.
[FT article and Sequoia slide deck found via Yves Smith]
A wave of job losses has started to spread across California’s Silicon Valley as the trademark optimism of the region’s technology start-ups has turned to pessimism amid the financial market rout.
The rapid reversal in mood has reawakened memories of the dotcom bust in 2001.
They also say that "Sequoia Capital ... [recently] greeted [entrepreneurs] with a presentation that began with a slide showing a gravestone and the words 'RIP good times' and were told to treat every dollar they spent as though it was their last."Please see also my January 2008 post, "The coming 2008 dot-com crash", the predictions there, and the many comments on that post.
[FT article and Sequoia slide deck found via Yves Smith]
Tuesday, October 21, 2008
Attacking tagging systems
A paper at WebKDD 2008, "Exploring the Impact of Profile Injection Attacks in Social Tagging Systems" (PDF), by Maryam Ramezani, JJ Sandvig, Runa Bhaumik, and Bamshad Mobasher claims that social tagging systems like del.icio.us are easy to attack and manipulate.
The paper looks at two types of attacks on social tagging systems, one that attempts to make a document show up on tag searches where it otherwise would not show up, another that attempts to promote a document by associating it with other documents.
Some excerpts:
Frankly, I have been surprised not to see more attacks on tagging systems. It may be the case that most of these sites lack a large, mainstream audience, so the profit motive is still not sufficiently high to motivate persistent attacks.
Please see also my earlier post, "Attacking recommender systems", that discusses another paper by some of the same authors.
The paper looks at two types of attacks on social tagging systems, one that attempts to make a document show up on tag searches where it otherwise would not show up, another that attempts to promote a document by associating it with other documents.
Some excerpts:
The goal of our research is to answer questions such as ... How many malicious users can a tagging system tolerate before results significantly degrade? How much effort and knowledge is needed by an attacker?The paper goes on to describe a few methods of attacking social tagging systems that require creating remarkably few fake accounts, as few as 0.03% of the total accounts in the system.
We describe two attack types in detail and study their impact on the system .... The goal of an overload attack, as the name implies, is to overload a tag context with a target resource so that the system correlates the tag and the resource highly ... thereby increasing traffic to the target resource ... The goal of a piggyback attack is for a target resource to ride the success of another resource ... such that they appear similar.
Our results show that tagging systems are quite vulnerable to attack ... A goal-oriented attack which targets a specific user group can easily be injected into the system ... Low frequency URLs are vulnerable to piggyback attack as well as popular and focused overload attacks. High frequency URLs ... are [still] vulnerable to overload attacks.
Frankly, I have been surprised not to see more attacks on tagging systems. It may be the case that most of these sites lack a large, mainstream audience, so the profit motive is still not sufficiently high to motivate persistent attacks.
Please see also my earlier post, "Attacking recommender systems", that discusses another paper by some of the same authors.
Monday, October 20, 2008
Digg shifting to personalized news
In a post by David Sarno at the LA Times, David describes Digg CEO Jay Adelson as using their new $28.7M round of funding to push "a renewed shift in personalizing content for individual users."
Update: It took a while but, a year and a half later, Digg is about to launch a new version of their site focused on personalized news.
Update: Two years later, finally, Digg launches its new website. As Mashable asks, too little too late?
Instead of showing users the most popular stories, [Digg] would make guesses about what they'd like based on information mined from the giant demographic veins of social networks. This approach would essentially turn every user into a big Venn diagram of interests, and send them stories to match.Please see also my older posts, "Digg recommendation engine" and "Combating web spam with personalization".
Adelson said Digg had not yet deployed local views of the content, but that it was in the planning stages. "We do believe the implicit groupings of users and interests that we use in the recommendation engine will certainly play a role in the future of Digg and how we can address localities and topics."
Update: It took a while but, a year and a half later, Digg is about to launch a new version of their site focused on personalized news.
Update: Two years later, finally, Digg launches its new website. As Mashable asks, too little too late?
Going to CIKM 2008
I will be attending CIKM 2008 in Napa next week. The conference looks quite interesting, especially the Industry Event with its impressive list of speakers.
If you will also be there, please say hello if you see me!
If you will also be there, please say hello if you see me!
Friday, October 17, 2008
Are advertisers rational?
Jason Auerback, Joel Galenson, and Mukund Sundararajan from Stanford had a paper at AdKDD 2008, "An Empirical Analysis of Return on Investment Maximization in Sponsored Search Auctions" (PDF).
Now, now, don't be put off by the frighteningly dull title. The paper is a fascinating look at whether people doing web advertising appear to be acting consistently and rationally in their bidding.
To summarize, in their data, advertisers do not appear to be bidding rationally or consistently.
Bidders very often have inconsistencies in their bidding on keywords over time that violate the ROI-maximizing strategy. The problem was most severe for advertisers that attempted to bid on many keywords. Only 30% of second-price auction bidders who bid on more than 25 keywords managed to keep their bids consistent over time. Only 19% of those bidders managed to maximize their ROI.
It looks like advertisers quite easily become confused by all the options given to them when bidding. 52% of the second price bidders they examined simply gave up and submitted essentially the same bid across all their keywords even if those keywords might have different value to them.
As Auerback et al. say, it may be the case that advertisers have neither "the resources or sophistication to track each keyword separately" or may "not have an accurate assessment of their true values per click on different keywords".
But this brings into question the entire ad auction model. In sponsored search auctions, we assume that advertisers are rational, able to manage bids across many keywords, and able to accurately predict their conversion rates from clicks to actions.
More work should be done here. This paper's analysis was done over small data sets. But, if this result is confirmed, then, as the authors say, a simpler system auction system, one with "improved bidding agents or a different market design" may result in more efficient outcomes than one that assumes advertisers have unbounded rationality.
Please see also my August 2007 post, "Self-optimizing advertising systems".
Wednesday, October 15, 2008
Google and personalized search at SMX
Googler Bryan Horling recently was on a panel with Danny Sullivan at SMX and talked about personalized search. A few people ([1] [2] [3]) posted notes on the session.
Not too much there, but one interesting tidbit is the way Google is thinking about personalization coming from three data sources, localization data (IP address or information in the history that indicates location), short-term history (specific information from immediately preceding searches), and long-term history (broad category interests and preferences summarized from months of history).
A couple examples were offered as well, such as a search for [jordans] showing the furniture store rather than Michael Jordan if the immediately preceding search was for [ethan allan], a search for [galaxy] showing LA Galaxy sports sites higher in the rankings if the searcher has a long-term history of looking at sports, and favoring web sites the searcher has seen in the past. Curiously, none of these examples worked as described when I tried them just now, but it is still interesting to think about it.
What I like best about what Bryan described is that the personalization is subtle, only doing minor reorderings. It uses the tidbits of additional information about your intent in your history to make it just a little bit quicker to find what you probably are seeking. It's a nice, low risk approach to experimenting with personalization, making only small changes that are likely to be helpful.
Tuesday, October 14, 2008
Review of SearchPerks
Danny Sullivan at Search Engine Land posts an insightful review of SearchPerks, Microsoft's new incentive program for Live Search, that includes a history of the rather dismal track record of other attempts to pay people to use a search engine.
Monday, October 13, 2008
Challenges from large scale computing at Google
Google Fellow Jeff Dean gave a fun talk last week at University of Washington Computer Science titled "Research Challenges Inspired by Large-Scale Computing at Google".
The talk is a "collection of problems we think are interesting/difficult" and, since it is coming from Jeff, has a heavy bias toward infrastructure problems.
The talk starts with energy efficiency in large scale clusters. Jeff pointed out that most work on power optimization is on laptops, not servers, but servers in a cluster have drastically different power optimization needs. In particular, laptops optimize power by shutting down completely, but servers are often at 20%-30% utilization on CPU, memory, and disk, and it would be nice to have them use only 20-30% power in this state rather than about 80%.
At this point, I was wondering why they didn't just shut down part of their cluster to get the utilization of the remaining servers closer to 80% or so. Ed Lazowska apparently was wondering the same thing since, moments later, he asked why can't Google just use smarter scheduling to compress the workload in the cluster (and, presumably, then put the now idle part into a low power mode). Jeff said that didn't work because it would impact responsiveness due to locality issues. Jeff's answer was vague and I am still somewhat unclear on what Jeff meant, but, thinking about it, I suspect what he wants is to use all the memory across all the boxes in the entire cluster, have a box respond immediately, but still use a lot less power when executing no-ops than the 50% of peak an idle box currently uses. So, keeping all the memory on the cluster immediately accessible so we can maximize how much data we can keep in memory seems like it is a big part of what makes this a challenging problem.
Next, Jeff talked about the OS. He pointed out that the "design point of the original version of Linux is pretty far removed from [our] very large data centers" and wondered if an operating system would be designed differently if it was specifically made for running in a cluster of 10k+ machines. He gave a few examples such as not really needing paging to disk but maybe wanting remote paging to the memory of other machines, adapting the network stack to microsecond network distances between machines, and changing the security model to focus on isolating apps running on the same box to guarantee performance.
Moving up a level again, Jeff described wanting a consistent framework for thinking about and building distributed applications and the consistency of the data for distributed applications.
Up one more level, Jeff wanted people to start thinking of having very large scale systems of 10M machines split into 1k different locations and how these would deal with consistency, availability, latency, failure modes, and adaptively minimizing costs (especially power costs).
Finally, Jeff briefly mentioned very large scale information extraction, speech processing, image and video processing, and machine learning, mostly talking about scale, but also giving a few examples such as moving beyond N-grams to handle non-local dependencies between words and Google's efforts to understand the semi-structured data in tables in web pages and data hidden behind forms on the Web.
Coming away from the talk, the biggest points for me were the considerable interest in reducing costs (especially reducing power costs), the suggestion that the Google cluster may eventually contain 10M machines at 1k locations, and the call to action for researchers on distributed systems and databases to think orders of magnitude bigger than they often are, not about running on hundreds of machines in one location, but hundreds of thousands of machines across many locations.
The talk is available for download in a variety of formats. Light, enjoyable, and worth watching if you are interested in large scale computing.
Friday, October 10, 2008
Designing GWAP
Luis Von Ahn and Laura Dabbish have an article in the August 2008 CACM on "Designing Games with a Purpose".
The paper has a nice overview of the goal of Games with a Purpose (GWAP), which is to produce useful output from the work done in games, and a good survey of some of the games available at gwap.com and the useful data they output.
If you've seen the GWAP work before, what is new and interesting about the article is the general framework they describe for building these types of games. In particular, the authors describe four generic types of guessing games, give examples of each class of games, and help guide those that are thinking of building their own games. In addition, Luis and Laura give a fair bit of advice on how to make the games enjoyable and challenging, how to prevent cheating, and techniques for mixing and matching human and computer players.
If you haven't seen GWAP before, go over to gwap.com and try a few games. My favorite is Verbosity, and Tag a Tune is good fun. I also think Tag a Tune is impressive as a demonstration of how games that label audio and video can still be quite fun even though they take a lot more time to play.
Thursday, October 09, 2008
Google describes perfect advertising
In a post titled "Ad Perfect", Googler Susan Wojcicki describes targeting ads as matching a deep understanding of a user's intent, much like personalized search.
Some key excerpts:
It appears to be a big shift away from mass market advertising and toward personalized advertising. This vision no longer has us targeting ads to people in general, but to each individual's intent, preferences, and context.
[Thanks, John Battelle, for the pointer to Susan's post]
Some key excerpts:
Advertising should deliver the right information to the right person at the right time ... Our goal is always to show people the best ads, the ones that are the most relevant, timely, and useful .... We need to understand exactly what people are looking for, then give them exactly the information they want.What strikes me about this is how much this sounds like treating advertising as a recommendation problem. We need to learn what someone wants, taking into account the current context and long-term interests, and then help them discover interesting things they might not otherwise have known existed.
When a person is looking for a specific item ... the best ads will give more specific information, like where to buy the item.
In other cases, ads can help you learn about something you didn't know you wanted ... [and to] discover something [you] didn't know existed.
One way to make ads better would be to customize them based on factors like a person's location or preferences.
It [also] needs to be very easy and quick for anyone to create good ads ... to measure [and learn] how effective they are .... [and then] to show them only to people for whom they are useful.
It appears to be a big shift away from mass market advertising and toward personalized advertising. This vision no longer has us targeting ads to people in general, but to each individual's intent, preferences, and context.
[Thanks, John Battelle, for the pointer to Susan's post]
Wednesday, October 08, 2008
Netflix Prize at KDD 2008
The Large Scale Recommender Systems and the Netflix Prize workshop was recently held at KDD 2008. I was not able to attend, but I still wanted to highlight a few of the papers from and related to the workshop.
Gavin Potter, the famous guy in a garage, had a short paper in the workshop, "Putting the collaborator back into collaborative filtering" (PDF). This paper has a fascinating discussion of how not assuming rationality and consistency when people rate movies and instead looking for patterns in people's biases can yield remarkable gains in accuracy. Some excerpts:
Galvin's paper is a light and easy read. Definitely worthwhile. Galvin's work forces us to challenge our common assumption that people are objective when providing ratings, instead suggesting that it is quite important to detect biases and moods when people rate on a 1..5 scale.
Another paper given in the workshop that I found interesting was Takacs et al, "Investigation of Various Matrix Factorization Methods for Large Recommender Systems" (PDF). In addition to the very nice summary of matrix factorization (MF) methods, the paper at least begins to address the practical issue of handling online updates to ratings, offering "an incremental variant of MF that efficiently handles new users/ratings, which is crucial in a real-life recommender system."
Finally, a third paper that was presented in the main KDD session, "Factorization Meets the Neighborhood: a Multifaceted Collaborative Filtering Model" (PDF), by Yehuda Koren from the leading Bellkor team, is an excellent discussion of combining different popular approaches to the Netflix contest. Some extended excerpts:
Finally, let me mention that the Netflix Prize is about to give its second progress prize. The current leader narrowed the gap between the grand prize and the last progress prize more than half over the last year. In conversations at the conference, people alternated between being hopeful that the remaining gap could be closed with a few new clever insights and despairing over the slow progress recently and questioning whether the grand prize is possible to win.
Gavin Potter, the famous guy in a garage, had a short paper in the workshop, "Putting the collaborator back into collaborative filtering" (PDF). This paper has a fascinating discussion of how not assuming rationality and consistency when people rate movies and instead looking for patterns in people's biases can yield remarkable gains in accuracy. Some excerpts:
When [rating movies] ... a user is being asked to perform two separate tasks.Gavin has done quite well in the Netflix Prize; at the time of writing, he was in eighth place with an impressive score of .8684.
First, they are being asked to estimate their preferences for a particular item. Second, they are being asked to translate that preference into a score.
There is a significant issue ... that the scoring system, therefore, only produces an indirect estimate of the true preference of the user .... Different users are translating their preferences into scores using different scoring functions.
[For example, people] use the rating system in different ways -- some reserving the highest score only for films that they regard as truly exceptional, others using the score for films they simply enjoy .... Some users [have] only small differences in preferences of the films they have rated, and others [have] large differences .... Incorporation of a scoring function calibrated for an individual user can lead to an improvement in results.
[Another] powerful [model] we found was to include the impact of the date of the rating. It seems intuitively plausible that a user would allocate different scores depending on the mood they were in on the date of the rating.
Galvin's paper is a light and easy read. Definitely worthwhile. Galvin's work forces us to challenge our common assumption that people are objective when providing ratings, instead suggesting that it is quite important to detect biases and moods when people rate on a 1..5 scale.
Another paper given in the workshop that I found interesting was Takacs et al, "Investigation of Various Matrix Factorization Methods for Large Recommender Systems" (PDF). In addition to the very nice summary of matrix factorization (MF) methods, the paper at least begins to address the practical issue of handling online updates to ratings, offering "an incremental variant of MF that efficiently handles new users/ratings, which is crucial in a real-life recommender system."
Finally, a third paper that was presented in the main KDD session, "Factorization Meets the Neighborhood: a Multifaceted Collaborative Filtering Model" (PDF), by Yehuda Koren from the leading Bellkor team, is an excellent discussion of combining different popular approaches to the Netflix contest. Some extended excerpts:
The two more successful approaches to CF are latent factor models, which directly profile both users and products, and neighborhood models, which analyze similarities between products or users.Like Gavin, Yehuda describes how to compensate for "systematic tendencies for some users to give higher ratings than others". Yehuda also discusses how implicit data on what users chose to rate and did not rate can be used for improving accuracy. And, Yehuda even addresses some of the differences between what works well in the Netflix Prize and what is necessary in a practical recommender system, talking about top-K recommendations, handling new users and new ratings without a full re-train of the model, using implicit feedback such as purchases and page views, and explaining the recommendations. Definitely worth the read.
Neighborhood models ... [compute] the relationship between items or ... users. An item-oriented approach evaluates the preferences of a user to an item based on ratings of similar items by the same user. In a sense, these methods transform users to the item space by viewing them as baskets of rated items .... Neighborhood models are most effective at detecting very localized relationships.
Latent factor models such as ... SVD ... [transform] both items and users to the same latent factor space ... [and] tries to explain ratings by characterizing both products and users on factors automatically inferred from user feedback. For example, when products are movies, factors might measure obvious dimensions such as comedy vs. drama, amount of action, or orientation toward children ... [as well as] less well defined dimensions such as depth of character development or "quirkiness" .... Latent factor models are generally effective at estimating overall structure that relates simultaneously to most or all users. However, these models are poor at detecting strong associations amount a small set of closely related items, precisely where neighborhood models do best.
In this work, we suggest a combined model that improves prediction accuracy by capitalizing on the advantages of both neighborhood and latent factor approaches.
Finally, let me mention that the Netflix Prize is about to give its second progress prize. The current leader narrowed the gap between the grand prize and the last progress prize more than half over the last year. In conversations at the conference, people alternated between being hopeful that the remaining gap could be closed with a few new clever insights and despairing over the slow progress recently and questioning whether the grand prize is possible to win.
Monday, September 15, 2008
KDD talk on advertising auctions
Michael Schwarz from Yahoo Research gave an invited talk at KDD 2008 on "Internet Advertising and Optimal Auction Design".
Much of the talk was background on first and second price auctions, but a particularly good discussion came at the end when Michael was talking about optimal setting of reserve prices for auctions.
A reserve price is the minimum bid for an advertiser to win an auction. Michael discussed how setting a reserve price correctly can significantly improve advertising revenue.
He did not cover the assumptions behind this claim in his talk, but details are available from his 2007 paper, "Optimal Auction Design in a Multi-unit Environment" (PDF). Briefly, setting the reserve price carefully can substantially increase advertising revenue when there are only a few bidders and when most bidders value a click well above the normal reserve price (e.g. most advertisers get $1 of value from a click but the default reserve price is $.05).
Michael also described a non-obvious effect where higher reserve prices indirectly impact top bidders because of price pressure from the now higher lower bids. Again, this is primarily is an issue of the reserve price substituting for lack of competition in the bidding, but still a useful thing to note.
After the talk, I chatted a bit with Michael about optimizing the reserve price for things other than immediate revenue. For example, we might want to optimize reserve price for user satisfaction, setting the reserve price at a level that effectively represents a high cost of user attention and filters out ads that users do not find worthwhile. Or, we might want to set our reserve price lower in the long tail of advertising keywords, making it cheaper (and bearing some of the risk) for advertisers as they try to gather information about how well their ads might work on more obscure keywords.
By the way, if you liked this post, you might also like one of Michael's other papers, "Internet Advertising and the Generalized Second Price Auction: Selling Billions of Dollars Worth of Keywords" (PDF). It is a fun paper that describes how current GSP advertising auctions do not actually force truth telling. The problem is rooted in the way there are multiple positions available and, if the lower positions still generate a good number of clicks, it can be advantageous for advertisers to offer lower bids.
Wednesday, September 03, 2008
KDD 2008 panel on the future of social networks
A panel at KDD 2008 called "Social Networks: Looking Ahead" was more remarkable for the questions it failed to answer than the ones it did.
One question that was repeatedly presented to the panel was how to make money off social networks. Underlying this question, and at least once stated explicitly, was the issue of whether social networks really matter or are just the latest flash in the pan, the latest bubble, and soon to fade if people find the riches they deliver fall short of their absurdly hyped expectations.
The best answer to this question came only at the very end, sneaking in when the session was already over, from panel chair Andrew Tompkins. Andrew said that he thought that what was most likely is that most money would be made from understanding an individual in a network and their immediate neighborhood. He expected that, as the space matured, the more theoretical work that we see now that looks at global patterns and trends across different types of social networks would continue, but the emphasis would shift to understanding each person in the network and from their behavior and their immediate neighbors to help people find and discover things they want.
Another question that came up and went largely unanswered was, are social networks really application specific? That is, are the patterns we see in one network (e.g. mobile) distinct from what we see in another (e.g. LinkedIn) because people use these tools differently? There was some evidence for this in one of the conference papers where there was a rather unusual distribution (PDF) reported in the contact lists of Sprint mobile customers because of how people use their mobile devices. The general issue here is that there is a different meaning of a link between people -- A friend? A colleague? Someone I e-mailed once? -- in each of these applications, so it is not clear that conclusions we draw from analyzing one social network generalize to others.
And this leads to another question, are social networks just a feature? That is, are social networks just a part of an application, not an thing worth anything by itself? For example, is our e-mail contact list only important in the context of e-mail? Is Facebook just a tool for communication, like IM, but not really best described as a social network? This came up a bit during the Q&A with the panel when someone suggested that perhaps we were just using one hammer -- graph analysis -- on every problem when the graph might not actually best capture what is important, the underlying activity in the application.
Though it was not discussed at all during the panel, two of the panelists focused their work on privacy, which made me wish I had asked, do we really have firm evidence that people care about privacy in these social applications? Instead, it seems people say they care about privacy but then freely give away private information when asked ([1]). From what I can tell, we do not really know to what extent privacy really matters to social networking application users, do we?
In the end, it seems many questions remain, some of them quite basic, on the where social networks are going. At this point, it is not even quite clear we know precisely what social networks are, much less whether they have an independent future.
Saturday, August 30, 2008
KDD talk on the Future of Image Search
Jitendra Malik from UC Berkeley gave an enjoyable and often quite amusing invited talk at KDD 2008 on "The Future of Image Search" where he argued that "shape-based object recognition is the key."
The talk started with Jitendra saying image search does not work well. To back this claim, he showed screen shots of searches on Google Image Search and Flickr for [monkey] and highlighted the false positives.
Jitendra then claimed that neither better analysis of the text around images nor more tagging will solve this problem because these techniques are missing the semantic component of images, that is, the shapes, concepts, and categories represented by the objects in the image.
Arguing that we need to move "from pixels to perception", Jitendra pushed for "category recognition" for objects in images where "objects have parts" and form a "partonomy", a hierarchical grouping of object parts. He said current attempts at this have at most 100 parts in the partonomy, but it appears humans commonly use 2-3 orders of magnitude more, 30k+ parts, when doing object recognition.
A common theme running through the talk was having a baseline model of a part, then being able to deform the part to match most variations. For example, he showed some famous examples from the 1917 text "On growth and form"
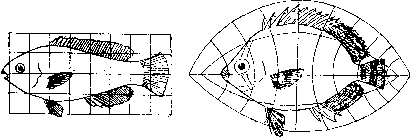
A near the end of the talk, Jitendra contrasted the techniques used for face detection, which he called "a solved problem", with the techniques he thought would be necessary for general object and part recognition. He argued that the techniques used on face detection, to slide various sized windows across the image looking for things that have a face pattern to them, would both be too computationally expensive and have too high a false positive rate to do for 30k objects/parts. Jitendra said something new would have to be created to deal with large scale object recognition.
What that something new is is not clear, but Jitendra seemed to me to be pushing for a system that is biologically inspired, perhaps quickly coming up with rough candidate sets of interpretations of parts of the image, discounting interpretations that violate prior knowledge on objects that tend to occur nearby to each other, then repeating at additional levels of detail until steady state is reached.
Doing object recognition quickly, reliably, and effectively to find meaning in images remains a big, hairy, unsolved research problem, and probably will be for some time, but, if Jitendra is correct, it is the only way to make significant progress in image search.
The talk started with Jitendra saying image search does not work well. To back this claim, he showed screen shots of searches on Google Image Search and Flickr for [monkey] and highlighted the false positives.
Jitendra then claimed that neither better analysis of the text around images nor more tagging will solve this problem because these techniques are missing the semantic component of images, that is, the shapes, concepts, and categories represented by the objects in the image.
Arguing that we need to move "from pixels to perception", Jitendra pushed for "category recognition" for objects in images where "objects have parts" and form a "partonomy", a hierarchical grouping of object parts. He said current attempts at this have at most 100 parts in the partonomy, but it appears humans commonly use 2-3 orders of magnitude more, 30k+ parts, when doing object recognition.
A common theme running through the talk was having a baseline model of a part, then being able to deform the part to match most variations. For example, he showed some famous examples from the 1917 text "On growth and form"
A near the end of the talk, Jitendra contrasted the techniques used for face detection, which he called "a solved problem", with the techniques he thought would be necessary for general object and part recognition. He argued that the techniques used on face detection, to slide various sized windows across the image looking for things that have a face pattern to them, would both be too computationally expensive and have too high a false positive rate to do for 30k objects/parts. Jitendra said something new would have to be created to deal with large scale object recognition.
What that something new is is not clear, but Jitendra seemed to me to be pushing for a system that is biologically inspired, perhaps quickly coming up with rough candidate sets of interpretations of parts of the image, discounting interpretations that violate prior knowledge on objects that tend to occur nearby to each other, then repeating at additional levels of detail until steady state is reached.
Doing object recognition quickly, reliably, and effectively to find meaning in images remains a big, hairy, unsolved research problem, and probably will be for some time, but, if Jitendra is correct, it is the only way to make significant progress in image search.
Friday, August 22, 2008
Column versus row stores
Daniel Abadi, Samuel Madden, and Nabil Hachem had a paper at SIGMOD 2008, "Column-Stores vs. Row-Stores: How Different Are They Really?" (PDF), with a fascinating discussion of what optimizations could be implemented in a traditional row store database to make it behave like a column store.
The paper attempts to answer the question of whether there "is something fundamental about the way column-oriented DBMSs are internally architected" that yields performance gains or whether the column-oriented optimizations can be mimicked in a row-store design.
Specifically, the authors look at taking a row-store and vertically partitioning the rows, indexing all the columns, creating materialized views of the data (just the needed columns for a query already precomputed), compressing the data, and a couple variations on late materialization when joining columns that significantly impact performance.
Despite strong statements in the abstract and introduction that "it is not possible for a row-store to achieve some of the performance advantages of a column-store" and that "there is in fact something fundamental about the design of column-store systems that makes them better suited to data-warehousing workloads", the discussion and conclusion further into the paper are far murkier. For example, the conclusion states that it "is not that simulating a column-store in a row-store is impossible", just that attempting to fully simulate a column-store is difficult in "today's row store systems".
The murkiness seems to come from the difficulty the authors had forcing a row-store to do some of the query plan optimizations a column-store does once they had jiggered all the underlying data to simulate a column-store.
For example, when discussing "index-only plans" (which basically means throwing indexes on all the columns of a row-store), the row-store used slow hash-joins to combine indexed columns and they "couldn't find a way to force [the system] to defer these joins until later in the plan, which would have made the performance of this approach closer to vertical partitioning".
Later, the authors say that they couldn't "trick" the row-store into storing columns "in sorted order and then using a merge join", so it instead did "relatively expensive hash joins". They say the problems are not fundamental and that "there is no reason why a row-store cannot store tuple headers separately, use virtual record-ids to join data, and maintain heap files in guaranteed position order", just that they were not able to force the row-store to do these things in their simulation.
In the end, the paper only concludes that:
Please see also two blog posts, "Debunking a Myth: Column-Stores vs. Indexes" and "Debunking Another Myth: Column-Stores vs. Vertical Partitioning", by the first author, Daniel Abadi, where he expands on some parts of the paper.
If you are interested in this topic, you might also enjoy two of my older posts, "MapReduce a step backwards?" and "C-Store and Google BigTable".
The paper attempts to answer the question of whether there "is something fundamental about the way column-oriented DBMSs are internally architected" that yields performance gains or whether the column-oriented optimizations can be mimicked in a row-store design.
Specifically, the authors look at taking a row-store and vertically partitioning the rows, indexing all the columns, creating materialized views of the data (just the needed columns for a query already precomputed), compressing the data, and a couple variations on late materialization when joining columns that significantly impact performance.
Despite strong statements in the abstract and introduction that "it is not possible for a row-store to achieve some of the performance advantages of a column-store" and that "there is in fact something fundamental about the design of column-store systems that makes them better suited to data-warehousing workloads", the discussion and conclusion further into the paper are far murkier. For example, the conclusion states that it "is not that simulating a column-store in a row-store is impossible", just that attempting to fully simulate a column-store is difficult in "today's row store systems".
The murkiness seems to come from the difficulty the authors had forcing a row-store to do some of the query plan optimizations a column-store does once they had jiggered all the underlying data to simulate a column-store.
For example, when discussing "index-only plans" (which basically means throwing indexes on all the columns of a row-store), the row-store used slow hash-joins to combine indexed columns and they "couldn't find a way to force [the system] to defer these joins until later in the plan, which would have made the performance of this approach closer to vertical partitioning".
Later, the authors say that they couldn't "trick" the row-store into storing columns "in sorted order and then using a merge join", so it instead did "relatively expensive hash joins". They say the problems are not fundamental and that "there is no reason why a row-store cannot store tuple headers separately, use virtual record-ids to join data, and maintain heap files in guaranteed position order", just that they were not able to force the row-store to do these things in their simulation.
In the end, the paper only concludes that:
A successful column-oriented simulation [in a row-store] will require some important system improvements, such as virtual record-ids, reduced tuple overhead, fast merge joins of sorted data, run-length encoding across multiple tuples ... operating directly on compressed data ... and late materialization ... some of ... [which] have been implemented or proposed to be implemented in various row-stores.That seems like a much weaker conclusion that what the introduction promised. The conclusion appears to be that a row-store can perform as well as a column-store on data warehouse workloads, just that it looks awkward and difficult to make all the optimizations necessary for it to do so.
Please see also two blog posts, "Debunking a Myth: Column-Stores vs. Indexes" and "Debunking Another Myth: Column-Stores vs. Vertical Partitioning", by the first author, Daniel Abadi, where he expands on some parts of the paper.
If you are interested in this topic, you might also enjoy two of my older posts, "MapReduce a step backwards?" and "C-Store and Google BigTable".
Subscribe to:
Posts (Atom)
